文章列表: 1 篇
2025-10-29
 Paper Reading
2025-10-29 ~ 2026-10-15
这里记录我读的paper,或是整篇文章,或是文章中最有insight的部分。
25.10.10
- CARFT: Boosting LLM Reasoning via Contrastive Learning with Annotated Chain-of-Thought-based Reinforced Fine-Tuning
- 用embedding 做contrastive learning,作为ReFT(PPO)的regular loss
- disadvantage:实验的数据集较为简单
RL w/o verifier
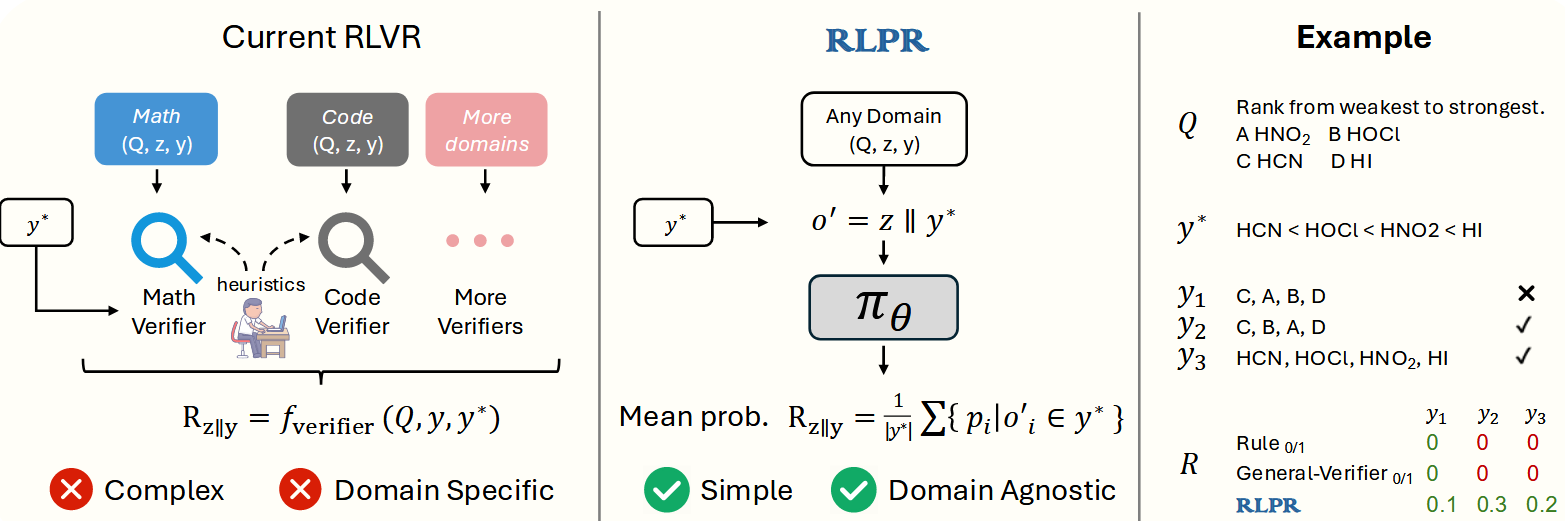
RLPR: Extrapolating RLVR to General Domains without Verifiers 25.10.29